MCP Server Discovery and Registry Patterns
How MCP servers went from manual config chaos to federated discovery infrastructure.
MCP server discovery has gone from a manual, copy-paste ritual to something resembling actual infrastructure, and this piece walks through how that infrastructure actually works: the official registry, the federation model built on top of it, the community directories that predate and now surround it, and the protocol-level tricks that might make central catalogs less necessary over time. None of these pieces are finished products. They're closer to a construction site with some scaffolding up and a few floors already occupied.
Before any of this existed, connecting to an MCP server meant hunting down an endpoint by hand, editing a JSON config file, checking whether the transport layer actually matched what the client expected, and wiring up authentication separately, one server at a time. People in the ecosystem started calling this a Byzantine process, and the label stuck because it was accurate: Cursor had its own deep-link install flow, VS Code wanted an mcp.json file, and other clients each expected their own configuration format. An AI agent trying to find a server on its own had no path to do so. Without structured metadata to read, it simply could not know what existed or what any given server could do.
Server authors had the opposite problem. There was no shared publishing path, so servers landed on npm, on PyPI, on Docker Hub, in GitHub repos, and occasionally in a forum thread that someone happened to bookmark. Multiple clients solved this the same way at the same time, by building their own "marketplace" tab, independently, with no shared upstream feeding any of them. The result was several duplicated, half-overlapping catalogs that disagreed with each other about what existed. Tens of thousands of servers accumulated with no shared index to make sense of them, and that fragmentation is the direct ancestor of every pattern this piece covers below: catalog registries, federation, and dynamic discovery are all attempts to patch a specific piece of the same underlying mess.
What a registry actually is and what it is not, the metadata-catalog distinction
A registry is a catalog of metadata about MCP servers: where a server lives, who published it, what it claims to do, and how to run it. It is not a host for the server's actual code. That distinction sounds pedantic until you trace where the artifacts actually sit: npm packages stay on npm, Python packages stay on PyPI, container images stay on GHCR or similar registries, and hosted endpoints stay behind whatever infrastructure their operator runs. The registry just stores enough installation detail, alongside the metadata, that a client can find and launch a server without knowing in advance where any of that lives.
Think of it as a library card catalog. The card tells you the book exists, who wrote it, and which shelf it's on. It does not hand you the book, and it definitely doesn't read it for you first.
That's worth sitting with, because it clarifies what a registry cannot do. It does not proxy runtime traffic. It does not execute tools on a server's behalf. And in its current form, the official MCP Registry does not audit live server behavior at all. A registry entry is a self-reported description, not a verified guarantee, and the gap between those two things matters more than it looks. A published manifest can describe a set of tools and capabilities that the actual running server no longer matches, whether from version drift, a bug, or something less innocent. Nothing in the metadata layer catches that on its own.
That said, this separation between metadata and runtime is exactly what makes federation possible later on. If a registry only stores pointers and descriptions, then other registries can copy, filter, and re-publish those pointers without touching a single line of the servers themselves. That's the architectural hinge the rest of this piece turns on.
The official MCP Registry: what launched, what it does, and where it still stands
The official registry launched in preview on September 8, 2025, with Anthropic, GitHub, PulseMCP, and Microsoft backing it. Its v0.1 API froze on October 24, 2025, and as of July 20, 2026 it's still labeled preview, which is either a sign of careful engineering or a sign that "preview" has become a permanent address rather than a waystation. Probably some of both.
It lives at registry.modelcontextprotocol.io, with a staging environment for anyone testing against it before going live. Organizations that want their own copy can pull the Docker image at ghcr.io/modelcontextprotocol/registry:latest and self-host an instance that speaks the same API.
The index currently holds around 2,000 servers, which sounds small next to community directories running into the tens of thousands. But that's by design, not by failure: the official registry positions itself as the authoritative upstream source, not a scraper vacuuming up anything with an install script attached.
Publishing works through a specific chain. A server author writes a server.json describing the endpoint, capabilities, versioning, and packages, then pushes it using the mcp-publisher CLI tool. Identity gets verified one of three ways: GitHub OAuth, GitHub OIDC for automated Actions workflows, or a DNS/HTTP challenge proving control of a domain.
On the query side, the API exposes a single main endpoint, GET /v0.1/servers, with a search parameter for filtering by term and an updated_since parameter that takes an RFC3339 timestamp for incremental syncing. That's a narrow surface on purpose. The registry isn't meant to be something a developer browses the way they'd browse an app store. It's meant to be infrastructure sitting underneath other things, a base layer that downstream directories and clients pull from and build curation on top of.
Which raises an obvious question: if most MCP clients haven't wired the registry's REST API into their own discovery flow yet, and are still leaning on manually edited JSON, does the registry actually change anything for the average user today? Mostly not directly. Its value shows up secondhand, through the platforms that consume it, rather than in whatever config screen a developer happens to be staring at this week.
Governance sits with a registry working group operating under a permissive open-source license. Moderation is a hybrid model: community members flag violations through GitHub issues, and maintainers review and denylist or remove entries by hand. The moderation model is community-driven rather than automated, a detail that becomes more relevant in a couple of sections.
Namespace verification as the registry's core trust mechanism
Here's the part that actually separates "found in the official registry" from "found in a random forum post from 2023." It's the provenance chain, and it runs through exactly two verification paths.
The first is GitHub OAuth or OIDC, which publishes a server under io.github.<username>/... Nobody can register something under that namespace without authenticating as the matching GitHub account, full stop. The second is domain proof: a reverse-domain namespace like com.example/... requires a DNS TXT record or an HTTP challenge demonstrating actual control of that domain.
The practical upshot: io.github.microsoft/some-server cannot be published by anyone except the account controlling Microsoft's GitHub identity. A lookalike registration under a similar-sounding namespace is a different string entirely and stands out as such, at least to anyone paying attention to the namespace rather than just the display name.
What this verification does not do is vouch for the server's actual safety. It doesn't confirm the code is free of bugs or malice, it doesn't check that the live tools/list response matches what the metadata claims, and it says nothing about how the server handles credentials once a client connects. Verifying who published something is a different question from verifying what that something does.
So the practical guidance for a developer evaluating a server: check the namespace and the artifact destination together. A vendor-controlled reverse-domain namespace, or an official organizational GitHub account, is stronger identity evidence than a personal account nobody's heard of. But that's a floor, not a ceiling, and sandboxing before handing over credentials remains the sane move regardless of how convincing the namespace looks. This layer is the direct architectural answer to the old problem of pasting install commands from an anonymous post and hoping for the best, and its absence is exactly what leaves a security gap open in several of the community directories covered further down.
How the federation model works: upstream registry, subregistries, and the flow of metadata
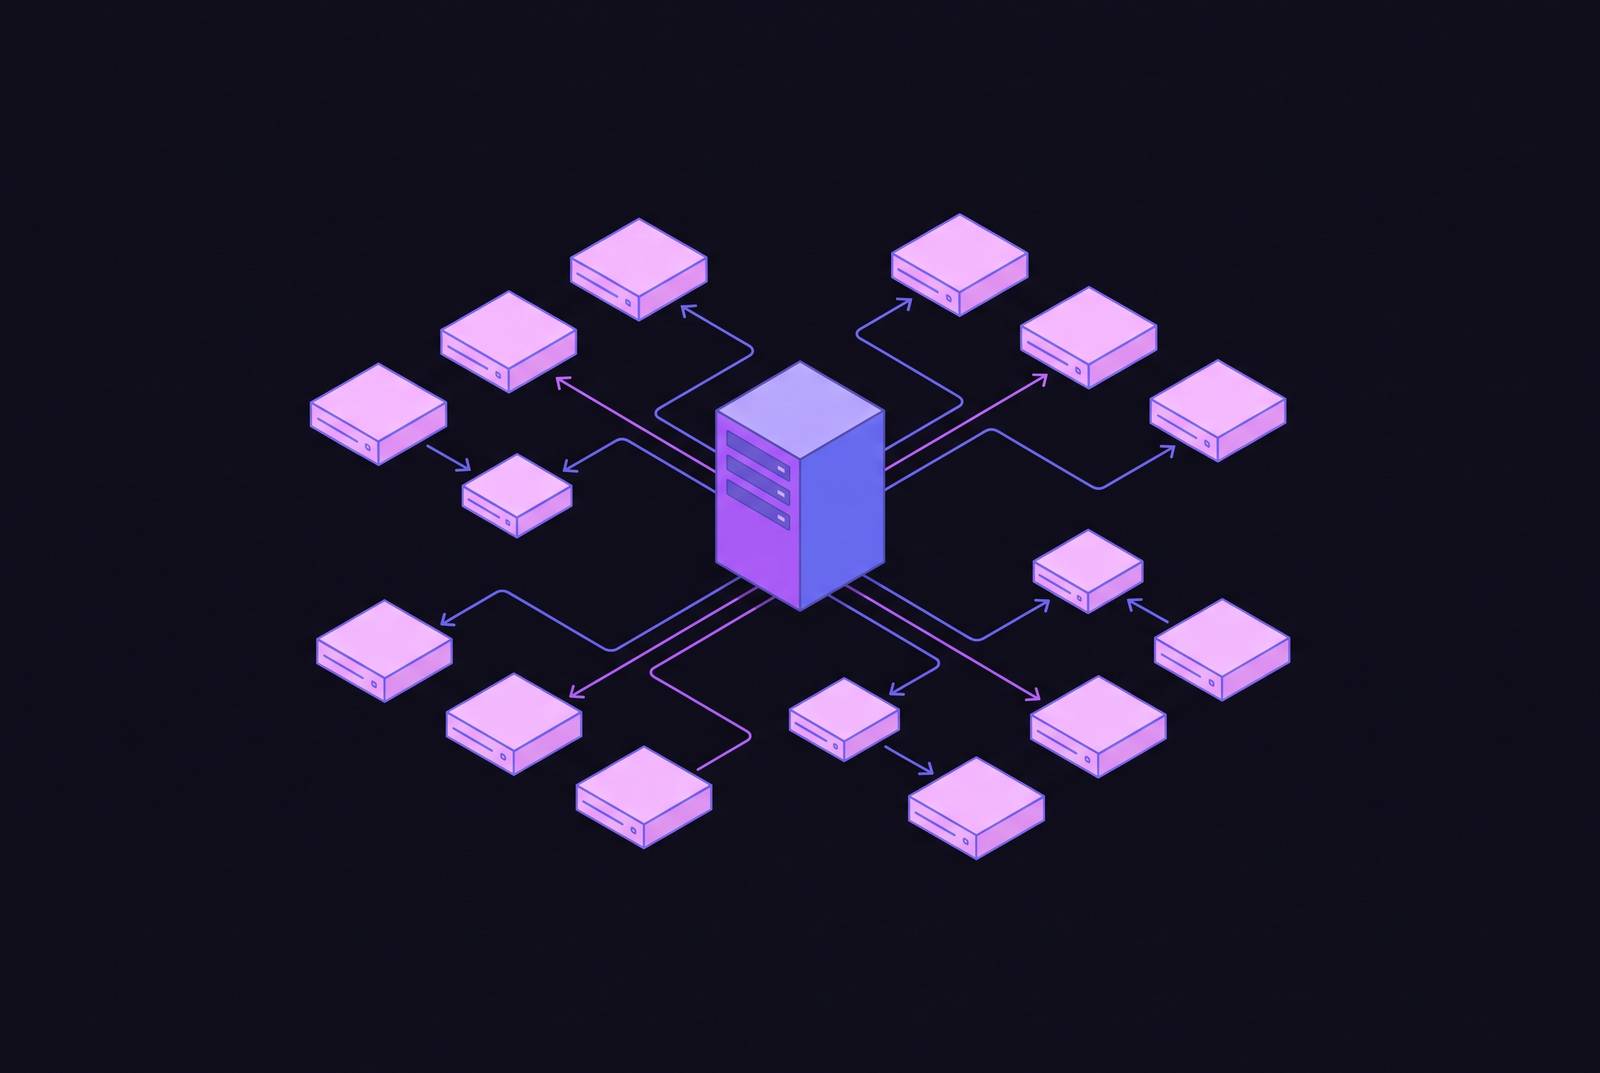
Federation isn't an accident of how the registry grew. It's a deliberate design decision: the official registry is meant to be canonical, not exclusive. Other registries are expected to sit downstream of it, ingesting its metadata and adding their own layer on top, rather than competing with it for the same ground.
Two kinds of subregistry have emerged from that design. Public subregistries are opinionated marketplaces tied to a specific client or community, pulling upstream metadata and adding ratings, search filters, and curation tuned to whoever's using that particular client. Private subregistries live inside organizations, blending public upstream servers with internally built ones, applying company access policy, and presenting a single consistent API to internal tooling.
What holds this together is a shared metadata contract. Subregistries that conform to the same schema allow SDKs and client libraries to keep working no matter which conforming registry sits behind them. That's the same trick that made web infrastructure interoperable for decades: agree on the interface, let implementations vary underneath it.
There's a governance payoff hiding in this model too. An organization can point its internal MCP clients exclusively at its private subregistry and restrict tool access to whatever's listed there, which is essentially the same allowlist logic GitHub Copilot already applies in practice. Downstream, various platform integrations have picked this pattern up, inventorying MCP servers and surfacing them through their own tool catalogs. Open-source projects have emerged doing something similar, offering self-hosted registry deployments for organizations that don't want to depend on external infrastructure. And for organizations that want the upstream registry itself, not just a subregistry pattern inspired by it, the same ghcr.io/modelcontextprotocol/registry:latest image supports running an internal instance.
But federation cuts both ways, and this is worth sitting with for a second. Publishing once to the upstream registry means a server becomes discoverable across every subregistry that ingests from it, which is the entire point. It also means that whatever data quality problems exist upstream get inherited by every single downstream consumer automatically. Federation doesn't just distribute discoverability. It distributes mess, too, at the same speed.
The data quality problem already visible in the official registry
Which brings up an inconvenient number. An analysis found that the registry's entries, tracing back to only a fraction of that count in unique underlying packages across npm, PyPI, and similar ecosystems, produce a volume of registry entries far exceeding that count, in a lopsided many-to-many pattern rather than a clean one-to-one mapping.
The mechanism behind that is almost boring in how simple it is. Publishing the same server, at the same version, more than once is currently permitted. CI pipelines that re-publish on every build end up generating a fresh duplicate entry each time instead of updating the existing one. Nobody's being malicious here. It's just a missing constraint, the software equivalent of a printer that keeps making copies because nobody told it the job was already done.
The consequence lands hardest on whoever's downstream. Subregistries mirroring the upstream feed ingest that noise right alongside the legitimate signal, which means every single downstream catalog has to independently solve a deduplication problem that really only needed solving once, at the source. The registry's own moderation model, community flagging through GitHub issues plus manual maintainer review, was built to catch malicious or abusive content. It was not built to catch structural duplication, and there's currently no automated dedup layer doing that job instead.
Worth remembering here: the registry is still in preview, and the launch materials explicitly do not promise data durability yet. Adopters were told to expect breaking changes before anything resembling general availability. So this isn't a scandal. It's closer to a bug tracker item that hasn't been prioritized, on a project that's honest about not being finished.
For anyone architecting a system on top of this feed, the takeaway is fairly mechanical: deduplicate on package identity, meaning the actual npm or PyPI package name and version, rather than trusting registry entry count as a proxy for how many distinct servers exist. Treat the upstream as a raw feed that needs cleaning, not a pre-curated catalog ready to display to end users.
The community directory landscape: what each major catalog offers and where it sits in the ecosystem
Five directories are worth knowing by name, and each one occupies genuinely different territory rather than just competing on raw size.
PulseMCP lists over 15,930 servers as of May 2026 and has built its reputation on freshness: it's typically the first place a newly launched server shows up, updated daily, and it updates daily and focuses on recently launched servers.
Smithery sits at roughly 7,300 servers and has a more specific origin story: founded in December 2024 by Henry Mao and Anirudh Kamath, and CTO at Jenni.ai, with backing from South Park Commons. By its own reporting, it grew from around ten servers at launch to more than 6,000 listed and hosted. What sets Smithery apart isn't the count, it's the model: one-click hosting plus a routing layer called Toolbox, a meta-MCP that directs agents to the right underlying server at runtime. That combination makes Smithery function something like Docker Hub for this ecosystem, the one place where discovery and actual deployment come from the same provider rather than being split across separate tools.
Composio takes a different angle entirely, framing itself around integration breadth: over 1,000 toolkits spanning more than 20,000 individual tools, oriented toward coverage of external services rather than a race to list the most raw MCP servers.
Some directories have taken a container-native approach, packaging servers as images distributed through existing container infrastructure. This model appeals to teams that want a vetted subset integrated with existing container workflows.
MCP.so is another community directory with a large server count, making it the largest unstructured collection in the space. Some entries carry a "featured" or "official" label, though the criteria behind those labels stay vague. It's the broadest surface available and, by the same token, the least curated one.
None of these five converge into a single unified index, and a server that's visible on PulseMCP might be entirely absent from Smithery or from the official registry itself. That's worth sitting with, because it means "searching MCP servers" isn't a single action yet, it's five different searches with five different blind spots. The official registry, despite having the fewest entries at around 2,000, remains the only one enforcing verified publisher namespaces. Everything else trades that verification for scale.
So the practical decision tree looks something like this: reach for the official registry when provenance is the thing that matters most, use PulseMCP when freshness and being first matters, use Smithery when hosting and runtime routing need to travel with discovery, and treat MCP.so as a volume source that demands independent vetting before anything gets near production credentials.
Protocol-level discovery: how servers can advertise themselves without a central catalog
Registries solve discovery by centralizing it. Three proposals currently in development try to solve the same problem by decentralizing it instead, each one borrowing a pattern that's already proven itself somewhere else on the internet.
The first is Server Cards at /.well-known/, defined under SEP-1649. The idea mirrors what OAuth 2.0 already does at /.well-known/oauth-authorization-server and what OpenID Connect does at /.well-known/openid-configuration: a client sends a single HTTP GET before ever opening a full MCP session, and gets back what tools, resources, and prompts the server offers, which transports it supports, and how authentication works. Servers aren't obligated to reveal everything up front either. Sensitive tool descriptions can be withheld, and tools can be marked "dynamic" if the server would rather not disclose them before a connection actually opens. CORS headers are required so browser-based clients can read the card directly. The proposed path is /.well-known/mcp/server-card.json.
The second is DNS TXT record discovery, currently an IETF Internet-Draft. It defines a _mcp.<domain> TXT record carrying the endpoint URL, transport protocol, cryptographic identity, and a capability profile. This isn't meant to replace HTTPS-based discovery so much as sit beside it: DNS lookups are cached by resolvers and don't require a full HTTPS round-trip, which matters in environments where that round-trip is expensive or where connectivity is unreliable. The reference implementation targets MCP specification version 2025-11, defaults to streamable-http as its transport, and treats DNSSEC, DANE, and IdentityLog together as a mandatory verification chain for any _alter. record, which is a fairly serious security posture for something that started as a lightweight bootstrap mechanism.
The third is the mcp:// URI scheme, defined in a separate IETF draft, which gives publicly reachable MCP servers a proper machine-to-machine identifier. It supports two discovery modes: /.well-known/mcp-server for broad compatibility, and DNS TXT for faster, DNS-native lookups. Manifest integrity is optional but supported through JSON Web Signatures under RFC7515, with the signing keys published via DNS. Before a connection even opens, the manifest can declare a trust class, authentication requirements, applicable compliance frameworks, and logging policy, which pushes a fair amount of security negotiation earlier in the process than most of today's clients currently bother with.
Here's the funny part, and it says something about how standards actually get made: SEP-1649 wants /.well-known/mcp/server-card.json, while the separate mcp:// URI draft wants /.well-known/mcp-server. Two proposals, drafted to solve the same problem, arrived at two different addresses for the same doorbell. Both drafting groups have acknowledged the mismatch and are talking about reconciling it, which is either the standards process working exactly as intended or a preview of the same fragmentation that made a central registry necessary in the first place. Possibly it's both, and that ambiguity might be the most honest note to end on: this ecosystem is still deciding whether the answer to fragmentation is a better catalog, a better protocol, or (most likely) some uneasy mixture of the two running side by side.
Sources
- Introducing the MCP Registry
- MCP Registry Architecture: A Technical Overview — WorkOS
- Best MCP Registries in 2026: Compared for Developers and Enterprises
- The State of MCP Registries
- github.com
- datatracker.ietf.org
- GitHub - modelcontextprotocol/registry: A community driven registry service for Model Context Protocol (MCP) servers.
- A Measurement Study of Model Context Protocol Ecosystem