Metadata Filtering to Improve Retrieval Precision
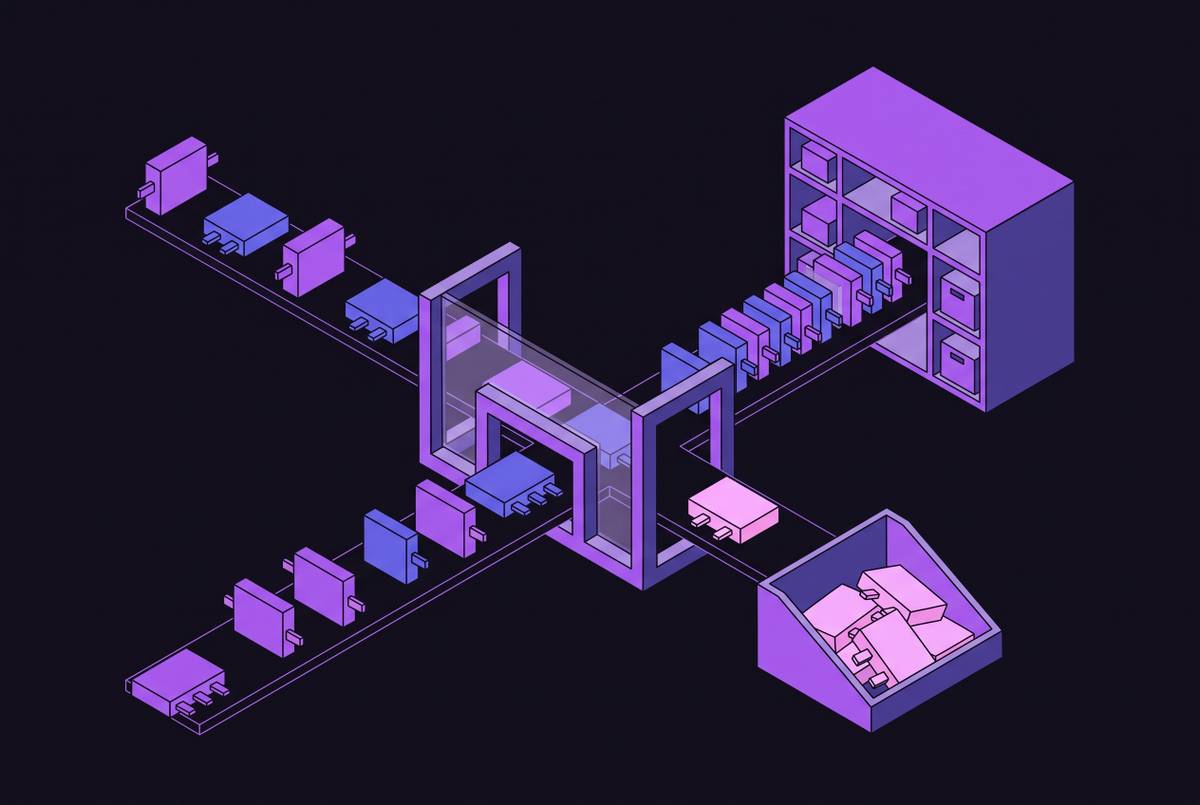
Filter metadata before vector search runs to prevent irrelevant results.
Maya Vance
Filter metadata before vector search runs to prevent irrelevant results.
Two retrieval methods catch what the other misses, boosting accuracy over either alone.
Match the workload to the database, not the benchmark, to build RAG systems that actually work.
Three cache layers demand different invalidation strategies to keep costs down.
Chunking matters as much as your embedding model—and most teams optimize the wrong layer.
Choose stateless for short tasks, stateful for long conversations.
Context isolation prevents token degradation as AI systems handle longer, more complex tasks.
Teams must evaluate agent trajectories and tool calls, not just final outputs.
LLM agents fail predictably at tool selection, not randomly.
Persistent memory layers, not bigger context windows, solve agent degradation.
Shared context stores are the load-bearing component that makes or breaks multi-agent coordination.
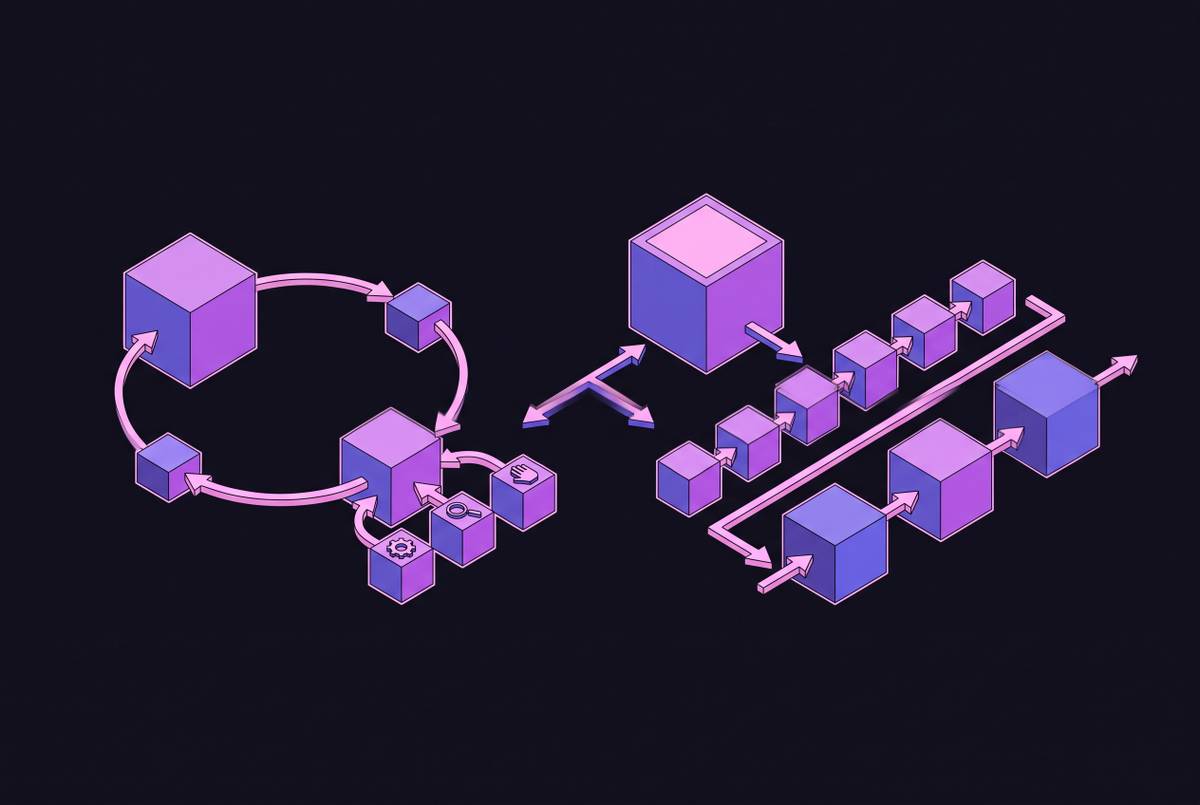
ReAct adapts step-by-step while Plan-and-Execute locks in the full sequence upfront.