Tool Selection Reliability in LLM Agents
LLM agents fail predictably at tool selection, not randomly.
Tool selection reliability in LLM agents fails at specific, identifiable points, not randomly. Retrieval gaps, over-privileged choices, and adversarial tool descriptions each break the pipeline in a different place, and each requires a different fix. Understanding where these failures live determines which fix applies, since retrieval gaps, over-privileged choices, and adversarial tool descriptions each require a different one, and the pool an agent meets in production is rarely the pool it was graded on.
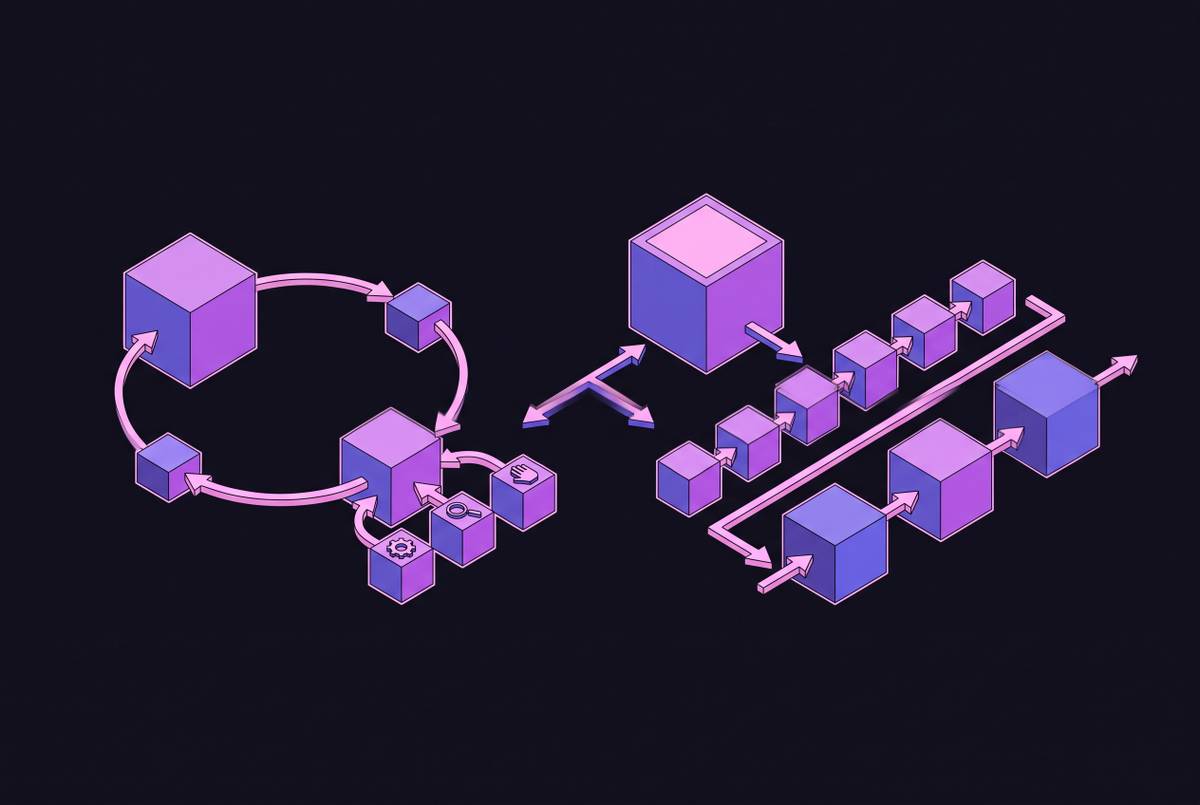
Most deployed agents can't hold their entire tool catalog in context at once. So the field settled on a two-stage pipeline: a retriever narrows the full pool down to a top-N slate, and a selector picks one tool from that slate using names, descriptions, and schemas. It sounds simple, but each stage fails on its own terms. Retrieval errors mean the wrong tools even show up. Selection errors mean the selector picks wrong from a slate that was actually fine. Parameter errors mean it picked correctly but filled in the wrong arguments. These are three separate problems, and treating them as one blurry "accuracy" number is part of why reliability keeps surprising teams after launch.
Open registries make this worse. A tool-publishing standard released in 2024 lets third parties publish tools an agent never encountered during training. Tools can be republished under new names. Near-duplicates can crowd a slate until legitimate options get buried. And because publishers write the metadata, some of it ends up optimized to get retrieved. That's the core reason benchmark numbers on a fixed, curated pool tell you so little: the pool an agent sees in a lab is not the pool it meets in the wild. The attack surface here has three parts working together: pools nobody regulates, a retriever the whole pipeline depends on, and metadata that drives selection outcomes on its own.
How retrieval selectivity collapses before the selector ever acts
Retrieval research out of Meta Platforms exposed a genuinely strange paradox: a system can report 99% success and still be adding nothing over random chance. Success, in the standard framing, just means the top-K contains at least one relevant result. That's a low bar, and this low bar causes total selectivity collapse while still producing a number that looks great on a slide.
The researchers introduced a metric called Bits-over-Random (BoR) to catch what success rate misses. On the 20 Newsgroups dataset, both BM25 and SPLADE cleared 99% success at K=100, yet BoR sat near zero. That gap means the retriever wasn't contributing meaningful signal at all; a random draw would have done almost as well. The mechanism is straightforward once you see it: when the ratio of relevant items to total catalog size is high, which is exactly the situation in the small-to-medium tool catalogs most agents actually work with, the odds of randomly landing on at least one relevant tool climb so fast that the retriever's real job, ranking, stops mattering.
The same paper confirms this collapse zone applies directly to LLM tool selection. Small catalogs are the norm, not the exception, for most agent deployments, and that's precisely where selectivity evaporates even with a selector that behaves perfectly downstream.
The obvious fix, retrieve more tools, doesn't work. Raising K raises the chance baseline at roughly the same rate, so BoR gains stay near zero while token costs climb. And token costs are not abstract here. Tool definitions can consume a substantial portion of the context window before the agent has read a single word from the user. In practice, even modest tool catalogs can generate tens of thousands of tokens in definitions alone. So even a retriever that performs flawlessly hands its slate to a selector that's already operating inside a context window stuffed with tokens, under exactly the density conditions where selectivity tends to disappear.
What certified correctness bounds reveal about how fragile current agents are
A framework called LLMCert-T, published by Yeon, Chaudhary, and Singh at the University of Illinois Urbana-Champaign (arXiv:2510.03992), is the first attempt to put a statistical ceiling on how safe a tool-selection pipeline actually is under realistic conditions. It doesn't estimate performance. It certifies, with high statistical confidence, an upper bound on the probability that a pipeline satisfies a declared safety specification.
The finding is stark. Across popular BFCL and OpenAPI tool pools, certified correctness bounds drop to a startlingly low roughly 20% under two specifications the researchers call Distractor Selection and Top-N Saturation. That's nowhere close to what clean-pool benchmark scores would suggest. And the framing matters here. A low upper bound isn't a pessimistic guess; it's a ceiling. It says the true satisfaction probability cannot be higher than this, no matter how good the model looks on a leaderboard.
Mechanically, LLMCert-T treats certification as a Bernoulli estimation problem. It draws inserted-tool sequences from a distribution fixed by the safety specification, runs the trials, and aggregates outcomes into a one-sided Clopper-Pearson bound. That statistical grounding is what makes the result actionable rather than another point estimate to argue over.
The paper states that tool-selection errors can produce outcomes like unauthorized data access without a single change to the model's weights. The risk lives in the pipeline architecture, not only in what the model has learned. BFCL-style benchmarks still have value for ranking models under controlled, matched conditions. But LLMCert-T's real contribution is showing that no pipeline tested so far achieves certified safety under the kind of registry conditions agents actually face. And the fragility isn't scattered randomly across the input space. It concentrates at two specific stress points, distractor saturation and top-N saturation, which is itself evidence that these are structural failure modes, not noise that better sampling would wash out.
Over-privileged tool selection turning task completion into a security risk
A benchmark called TOOLPRIVBENCH (Yang et al., arXiv:2606.20023v2) is the first one built specifically to catch a failure mode that isn't visible in a wrong answer: an agent completing the task correctly, but through a tool with far more access than the task required. It covers 8 domains, 5 risk types, and 544 validated scenarios, and its design choice matters a lot. Every scenario gives the agent both a lower-privilege and a higher-privilege tool, each independently capable of finishing the task. That removes the usual excuse. The low-privilege tool genuinely works. The agent just doesn't reach for it.
The results reveal that agents frequently reach for higher-privilege tools even when lower-privilege alternatives are available and sufficient, and that transient execution failures in particular tend to trigger escalation to more permissive options even when a retry of the original tool would have succeeded.
The paper's finding is that over-privileged selection appears across mainstream LLM agents, and that transient failures sharply amplify escalation. An agent's commitment to the least-privilege option apparently doesn't hold up well under execution stress. Standard safety alignment doesn't transfer reliably to this problem. Prompt-level instructions ("prefer the lower-privilege tool") help some, but the effect weakens fast in multi-turn conversations, which is exactly where premature escalation tends to happen.
What does work, according to the paper, is privilege-aware post-training: explicitly teaching the agent to prefer sufficient lower-privilege tools and escalate only when actually necessary. That approach cuts unnecessary high-privilege use substantially while holding general task performance steady.
The paper draws a comparison that deserves attention. Production software has a long history of "vibe coding," apps that function correctly in every visible way while quietly running on overly permissive backend access. Over-privileged tool selection is the agent-layer version of the same problem: a storage bucket left open, except the misconfiguration lives in which tool the agent decided to call. The task gets done. That's not the issue. It got done through a channel wide enough to make any downstream error, misuse, or compromise far more damaging than it needed to be.
Adversarial tool descriptions manipulating the selector without touching the model
Metadata is the attack surface nobody has to touch the model to exploit. In open registries, a tool's name, description, and schema can be written to game retrieval and selection rather than to describe what the tool actually does. This threat is not purely theoretical: open registries with publisher-controlled metadata create conditions where such manipulation is structurally possible.
Three distinct vectors appear in MCP-style registries. Tool poisoning is the injection of malicious tools directly into the pool, positioned to intercept task execution. Indirect prompt injection hides instructions inside a tool's description text, instructions the selector then reads and acts on as if they came from the user. Metadata manipulation is quieter: description text engineered to surface ahead of legitimate alternatives during retrieval, then win selection once it's in the slate.
None of this requires touching model weights. The selector makes its decision by reading natural-language metadata, so rewriting a name or a description changes the outcome directly. LLMCert-T's own diagram of the attack surface treats this as the third source of variability in the pipeline, alongside unregulated pools and retriever dependence.
A separate effort called MCP-AgentBench (arXiv:2509.09734, September 2025) tries to evaluate agent performance across MCP-mediated tool interactions, both single-server and multi-server tasks, using LLM-assisted query generation checked by humans. Scalable, cross-server evaluation across real-world MCP ecosystems, with genuinely complex tasks, remains an open problem in the field.
Near-duplicate saturation compounds all of this. A publisher, malicious or just careless, floods the slate with tools that all look semantically similar, crowding out legitimate options before the selector even gets a fair look at them. Top-N Saturation is one of the two specifications under which LLMCert-T found certified bounds collapse to about 20%, and that's not a coincidence. Registry governance, deciding what tools get published and validating their descriptions before they enter the pool, is a reliability concern in its own right. No amount of clever selection logic downstream fully compensates for a pool that was poisoned upstream.
What diagnostic benchmarks actually measure
The Berkeley Function-Calling Leaderboard, or BFCL, is the most widely cited benchmark for this space. It checks whether a model generates valid function calls, correct argument structure, correct API choice, and appropriate abstention when no tool fits, across 2,000 question-answer pairs spanning multiple languages and domains. It's a genuinely useful tool for comparing models under matched conditions. But it runs on fixed, curated pools, which is exactly the condition LLMCert-T shows is a poor predictor of certified safety once a pipeline meets a realistic, adversarial registry.
A newer benchmark, ToolFailBench, takes a different approach: instead of one aggregate success number, it separates out four named failure modes. Tool-Skip is when the agent bypasses invoking a tool. Result-Ignore is when it calls the tool but doesn't actually use the output in its answer. Output-Fabrication is when it answers without grounding the response in any tool result at all. Unnecessary-Tool-Use is when it calls a tool for a task that didn't need one. Such frameworks typically span multiple professional domains and include both tool-required tasks and control tasks designed to catch fabrication.
TOOLPRIVBENCH adds a fifth dimension that neither BFCL nor ToolFailBench was built to catch: privilege escalation. A survey presented at KDD 2025 (Mohammadi, Li, Lo, Yip, arXiv:2507.21504) identifies the broader gap here. Enterprise concerns, role-based access to data, audit and compliance guarantees, reliability over long-horizon multi-turn interactions, rarely appear in existing evaluation frameworks at all. Most of these tools were built to evaluate research prototypes.
A high BFCL score answers one narrow question: does this model generate syntactically valid calls against a clean, controlled pool? It doesn't say anything about how the pipeline behaves under an adversarial pool, under privilege pressure, or across a long multi-turn session under execution stress. Those are different questions, and right now, mostly different benchmarks.
Structural mitigations that address failure modes at the layer where they originate
Fixes are most direct when applied at the layer where the failure actually starts, since interventions at a different stage must compensate for upstream problems they were not designed to address.
At the retrieval layer, graph-based tool organization directly targets the growth in catalog size that drives selectivity collapse. ControlLLM (Liu et al., 2024) builds a graph where tools and resources are nodes and edges capture input-output relationships, then searches that graph for toolchains that satisfy decomposed subtasks. That shrinks the selector's actual job down to a constrained subgraph instead of the full, sprawling pool. ToolNet (Liu et al., 2024) takes a related approach, organizing large tool sets into a weighted directed graph that updates based on prior usage, which chips away at the same catalog-size dynamic that drives BoR toward zero.
At the model-behavior layer, privilege-aware post-training is the mitigation TOOLPRIVBENCH shows actually moving the needle, cutting unnecessary high-privilege selection substantially while keeping task performance intact, and outperforming prompt-level controls especially once conversations run multi-turn.
At the pool layer, registry governance, validating descriptions, vetting publishers, catching near-duplicates before they ever enter the catalog, is the only thing that addresses adversarial metadata at its source. Nothing downstream fully makes up for a pool that was already compromised going in.
At the measurement layer, reporting BoR alongside traditional success metrics gives practitioners a way to see when deeper retrieval (a bigger K) is buying nothing but token cost. And at the certification layer, LLMCert-T gives teams an actual statistical bound on pipeline safety under a declared specification, turning "is this reliable" from a vibe into a number that can be tracked across model versions and mitigation attempts.
Real gaps remain. Scalable, cross-server evaluation across live MCP ecosystems is still unsolved. Multi-turn privilege escalation under execution stress is only partly addressed by today's prompt-level controls. And as the SAP Labs survey points out, no single framework yet evaluates behavior, capability, reliability, and safety together in one place. Each piece of this problem has a home. None of it has a roof yet.